close

Evan Pip

Technology

Smart Studios, Smarter Bodies: How Technology Is Reshaping the Pilates Reformer Experience in Singapore

Fitness technology has transformed almost every aspect of how people train, monitor, and understand their bodies. From heart rate monitors strapped to wrists to AI-generated training plans delivered through smartphone apps, the modern exerciser in Singapore has access to more performance data and personalised insight than any previous generation. Yet for many years, the world of Pilates remained a relative outlier in this technological shift, priding itself on the attentiveness of human instruction and the nuance of tactile correction over digital measurement.

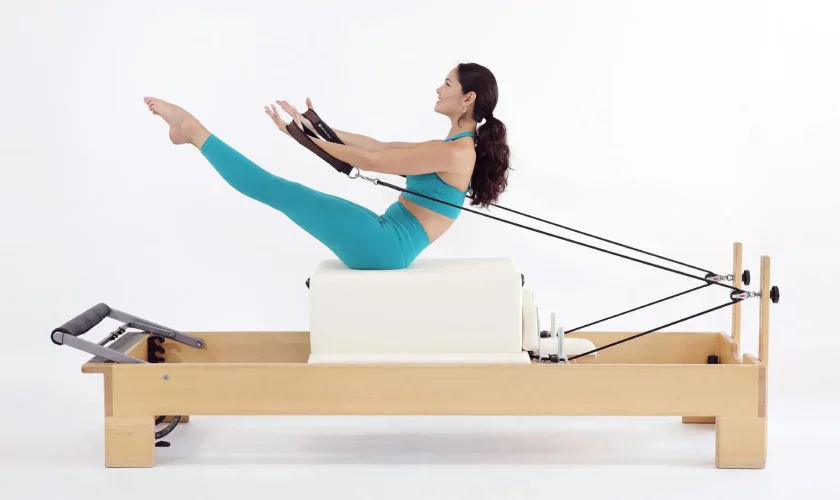
That gap is closing rapidly. The integration of technology into the pilates reformer experience is no longer a future scenario. It is actively reshaping how studios design sessions, how instructors identify technique errors, how clients track their progress, and how Pilates businesses operate in an increasingly data-literate fitness market. Singapore, with its high smartphone penetration, strong technology adoption culture, and discerning fitness consumer base, is at the forefront of this integration.

Movement Analysis Technology: From Eye to Algorithm

Traditionally, movement quality assessment in Pilates has depended entirely on the trained eye of an experienced instructor. This is a genuinely skilled ability developed over years, and it remains irreplaceable in many contexts. But human visual assessment has inherent limitations. An instructor teaching a class of eight people cannot simultaneously monitor the pelvic position, spinal alignment, foot placement, and breath pattern of every participant at every moment. Fatigue in a late-session exercise may go unnoticed until it has already produced a compensation pattern.

Computer vision and artificial intelligence are beginning to address these limitations. Movement analysis platforms using camera-based tracking can now monitor joint angles, movement velocity, symmetry ratios between left and right limbs, and alignment parameters in real time. In Reformer Pilates, this technology can be configured to flag when the lumbar spine moves out of neutral during footwork, when the pelvis rotates asymmetrically during leg press, or when the shoulder girdle elevates under load in the arm series.

This information can be displayed to the instructor on a monitoring screen, allowing them to provide targeted correction to specific clients without constantly scanning the room visually. It can also be shared with the client after the session as a movement report, providing tangible and objective evidence of what was performed well and where attention should be directed in future sessions.

Wearable Biofeedback in the Reformer Environment

Wearable technology has evolved significantly beyond simple step counting and heart rate monitoring. Electromyography-based wearables, which measure the electrical activity of specific muscles during exercise, are increasingly finding application in rehabilitation and performance training settings. In the reformer context, these devices can confirm whether the transversus abdominis and pelvic floor are activating appropriately during core-focused exercises, or whether the superficial abdominals are dominating.

This is particularly valuable in the early stages of reformer training, when clients are learning to access the deep stabiliser system and when the sensations of correct internal engagement are unfamiliar and difficult to distinguish from superficial muscle activity. Real-time biofeedback transforms this abstract instruction into visible, measurable data. When the display shows the deep stabiliser activating, the client can learn to recognise and reproduce the internal sensation that accompanies it. When the display shows the superficial muscles firing instead, the client has immediate and objective confirmation that the adjustment their instructor suggested is necessary.

Wearable pressure sensors designed for pelvic floor monitoring also have applications in the reformer setting, particularly for clients who are post-partum, perimenopausal, or managing pelvic floor dysfunction. These devices can confirm whether the pelvic floor is coordinating with the diaphragm and transversus abdominis during the breath-movement sequences that are central to Reformer Pilates methodology.

Smart Reformer Equipment: The Connected Machine

The reformer machine itself is becoming smarter. Next-generation reformer designs are beginning to incorporate embedded sensors that measure carriage velocity, spring resistance calibration, force distribution across the footbar, and the duration and consistency of each repetition. This data stream allows for a level of session quantification that was previously impossible.

For studios, connected reformer equipment provides aggregate data on how different client populations are using the machines, which spring configurations are most commonly associated with technique errors, and which exercises show the highest variability between clients. This information can inform curriculum design and instructor training in ways that pure observational experience cannot.

For individual clients, the data from a smart reformer session can be synced to a training app, allowing progress to be tracked across sessions with objective metrics rather than subjective memory. A client who has been working to improve left-right symmetry in their footwork over three months can see their symmetry ratio trending toward balance, providing the kind of concrete progress evidence that sustains motivation through the plateau periods that are a normal part of physical development.

App-Based Class Management and Personalised Programming

Studio management technology has transformed the administrative and client-facing dimensions of the Reformer Pilates business. Booking systems that were once managed through phone calls and paper schedules are now sophisticated digital platforms that track attendance history, preferred class times, instructor preferences, and membership status. But the more significant development is the emergence of app features that extend the studio-client relationship beyond the session itself.

Progressive studios in Singapore are beginning to offer app-based supplementary content including technique video libraries keyed to the exercises clients have been introduced to in class, guided at-home movement practices that complement reformer session work, and personalised focus notes from instructors delivered through the app following each session. This extends the value of each reformer session and supports the neuromuscular learning process between studio visits.

The data collected through app interactions also allows studio operators to identify which clients are engaging regularly, which are at risk of dropping attendance, and which may be ready to progress to more advanced class formats. This enables proactive client communication that feels personalised rather than automated, which is critical in a high-touch service environment like boutique fitness.

Virtual and Hybrid Reformer Instruction

The COVID-19 period accelerated experimentation with virtual fitness delivery across all modalities, with mixed results. For Reformer Pilates specifically, the limitations of virtual instruction became immediately apparent: without a reformer at home, clients could not replicate the session, and the tactile correction that is fundamental to reformer instruction cannot be delivered through a screen.

However, hybrid models have emerged that leverage technology more intelligently. Live-streamed reformer classes with camera angles specifically configured to show technique from multiple perspectives allow remote participants with home reformers to follow along with a degree of instruction quality that early virtual formats could not provide. Pre-recorded technique libraries, delivered through studio apps, allow clients to revisit cuing and instruction between sessions in a format that reinforces in-studio learning.

For studio-based sessions, technology that allows clients to record brief clips of specific exercises for technique review later, or to receive annotated video feedback from instructors after sessions, is bridging the gap between the in-room instruction moment and the ongoing learning process.

Data Privacy and the Ethics of Fitness Technology

As fitness technology in the reformer environment becomes more sophisticated, data privacy considerations become correspondingly important. Movement data, biometric information, health history details, and attendance patterns all represent sensitive personal information. Studios that collect this data have an obligation to handle it in accordance with Singapore’s Personal Data Protection Act and to be transparent with clients about what is collected, how it is stored, and how it is used.

The most trustworthy studios in Singapore’s Reformer Pilates landscape are those that treat data privacy not as a compliance checkbox but as a genuine dimension of client trust. Technology should serve the client’s development and safety, and clients should always have visibility into and control over their personal data.

Yoga Edition integrates technology thoughtfully into its studio experience, combining the irreplaceable quality of skilled human instruction with digital tools that extend client service and enhance outcome quality, always with a client-centred approach to how information is handled and used.

FAQ

Q: Do I need any wearable devices or special equipment to attend a tech-enabled Reformer Pilates class in Singapore?

A: In most cases, no. The technology used within the studio environment, including movement tracking systems and smart reformer equipment, is provided and managed by the studio. Clients typically need only a smartphone to access the studio’s booking and supplementary content app. Some studios may offer optional wearable device integration for clients who want additional biometric data, but this is generally not required for participation.

Q: How accurate is AI movement analysis compared to an experienced human instructor?

A: Current AI movement analysis systems are highly accurate for detecting gross alignment deviations and asymmetries, particularly when camera angles are optimised for the specific exercises being performed. However, they cannot replicate the full scope of an experienced instructor’s assessment, which integrates visual information with auditory cues, tactile feedback, and the clinical reasoning that comes from years of working with diverse bodies. The most effective application of AI movement analysis is as a complementary tool that enhances instructor capacity rather than a replacement for human expertise.

Q: I am concerned about my movement data being recorded during sessions. What should I ask a studio before enrolling?

A: Reasonable questions to ask include: what data is collected during sessions, how it is stored and for how long, whether it is shared with third parties, how you can access or delete your data, and what security measures protect it. A reputable studio should be able to answer these questions clearly and should have a published privacy policy aligned with Singapore’s Personal Data Protection Act requirements.

Q: Can technology help me progress faster in Reformer Pilates compared to traditional instruction alone?

A: The evidence from movement science research suggests that real-time biofeedback accelerates motor learning for complex movements, which is exactly what Reformer Pilates involves. Being able to see objective data confirming when you are executing a movement correctly, rather than relying solely on sensory feedback that may be unreliable in the early stages of learning, can meaningfully reduce the time needed to develop consistent technique. Technology does not replace the quality of instruction but can enhance the efficiency with which instruction translates into embodied skill.

Q: Are there any Reformer Pilates apps available in Singapore for home practice between studio sessions?

A: Several global Pilates platforms offer app-based content that includes reformer-adjacent bodyweight programming for between-session practice. Additionally, some Singapore studios have developed proprietary app content for their members. The most effective approach combines studio-specific supplementary content, which is calibrated to the exercises and progressions you are working through in class, with the core sessions themselves. Ask your studio whether they provide any digital content as part of your membership.
read more
Technology

How Fitness Technology Is Changing the Gym Experience in Singapore

Singapore has built its national identity in part around technological leadership. The Smart Nation initiative, world-class digital infrastructure, and a population with among the highest rates of smartphone penetration and wearable device adoption in Asia have created a population uniquely positioned to benefit from the intersection of technology and personal health. For Singapore gym-goers, fitness technology has moved well beyond the novelty phase. At a well-equipped gym Singapore members train at today, technology is integrated into the experience at multiple levels, from how sessions are booked to how body composition is tracked, how performance data is collected, and how personal training is personalised. Understanding what is available and how to use it purposefully separates gym-goers who drift from those who progress consistently.

InBody Analysis: From the Scale to Real Data

The bathroom scale is one of the most misleading tools in fitness. It tells you your total mass but cannot distinguish between fat, muscle, water, and bone. A gym-goer who is losing fat and gaining muscle simultaneously may see no change on the scale while their body composition is improving significantly. Conversely, someone who is losing muscle through crash dieting may see the scale move favourably while their metabolic health deteriorates.

InBody analysis, available at established Singapore gyms, uses bioelectrical impedance analysis (BIA) to provide a detailed breakdown of body composition that a scale cannot offer. An InBody assessment takes approximately 60 seconds and produces a report including:

  • Total skeletal muscle mass and segmental muscle distribution across the arms, trunk, and legs
  • Body fat mass and body fat percentage
  • Visceral fat level, which is the fat surrounding internal organs and a key metabolic health indicator
  • Total body water including intracellular and extracellular fluid distribution
  • Basal metabolic rate estimate based on lean mass

For Singapore gym-goers, the value of InBody analysis is in tracking change over time rather than interpreting a single reading in isolation. Repeating the assessment every four to eight weeks under consistent conditions, same time of day, same hydration state, creates a data record that reveals whether training and nutrition are producing the desired body composition changes regardless of what the scale shows.

Visceral fat tracking in particular is one of the most clinically relevant outputs for Singapore’s population given the city’s elevated rates of metabolic syndrome and type 2 diabetes. Visceral fat responds well to consistent exercise and dietary improvement, and InBody tracking makes this change visible in a way that external appearance often does not.

Wearable Technology: How Singapore Gym-Goers Are Training Smarter

Singapore’s wearable adoption rate is among the highest in Southeast Asia. Apple Watch, Garmin, Polar, Whoop, and Oura Ring are common sights in Singapore gyms, and the data these devices generate is increasingly being used purposefully rather than passively collected and ignored.

Heart rate monitoring The most fundamental use of wearable technology in training is heart rate monitoring during exercise. Training in specific heart rate zones determines the physiological adaptation the session produces. Zone 2 training, 60 to 70 percent of maximum heart rate, primarily develops aerobic base and fat oxidation capacity. Zone 4 and 5 training, 85 to 100 percent of maximum heart rate, targets cardiovascular capacity and VO2 max. Without heart rate data, intensity is a guess. With it, intensity becomes a training variable that can be precisely managed.

Heart Rate Variability (HRV) HRV is the variation in time intervals between successive heartbeats. It is a reliable indicator of autonomic nervous system balance and recovery status. When HRV is high, the parasympathetic nervous system is dominant, which correlates with good recovery and readiness for high-intensity training. When HRV is low, the sympathetic nervous system is dominant, often indicating accumulated fatigue, illness, or stress.

Singapore gym-goers using devices that track HRV, particularly Whoop and Garmin’s training readiness feature, can make data-informed decisions about when to push hard and when to back off or focus on recovery work. For Singapore’s overworked professional population, where distinguishing between productive training stress and counterproductive overreaching is genuinely challenging, HRV provides an objective signal that reduces guesswork.

Sleep tracking Sleep is where physical adaptation primarily occurs. Muscle protein synthesis, hormonal restoration, and neural consolidation of skill patterns all happen predominantly during deep and REM sleep stages. Singapore’s population consistently under-sleeps relative to requirements, and wearable sleep tracking makes this deficit visible rather than abstract.

Tracking sleep quality alongside training performance allows gym-goers to observe the direct relationship between sleep and session output, a connection that motivates better sleep hygiene in a way that general advice about sleep importance rarely does.

App-Based Class Booking and Training Consistency

One of the most practically impactful pieces of fitness technology for Singapore gym-goers is the ability to book group fitness classes through apps or digital platforms in advance. This might seem mundane compared to body composition scanners and HRV monitors, but the behavioural impact is significant.

Pre-booking a class creates a form of commitment that open gym access does not. When you have reserved a spot in a 7am cycling class that fills up, you face a specific social cost from not attending that simply visiting the gym floor does not replicate. Research on behaviour change consistently shows that implementation intentions, concrete plans about when, where, and how you will act, dramatically improve follow-through compared to vague intentions.

Singapore’s gym class booking platforms allow members to plan their training week in advance, set reminders, and receive notifications that support habit formation. For busy Singapore professionals whose schedules are disrupted constantly by meetings, travel, and work demands, having their training scheduled as firmly as a client meeting creates a structural commitment that casual gym intentions cannot replicate.

Technology in Personal Training: Data-Driven Coaching

Personal training in Singapore’s established gyms has become increasingly data-informed as trainers gain access to clients’ wearable data, InBody assessment histories, and digital training logs. This shift from intuition-based to data-informed coaching meaningfully improves programme quality.

A personal trainer who can review a client’s HRV trends, sleep quality, and training load data from the past four weeks has a far more complete picture of their client’s capacity and recovery status than one relying on verbal check-ins alone. This allows programme adjustments based on objective recovery data rather than estimates.

Progressive overload, the systematic increase of training stimulus over time that drives adaptation, is far more precisely managed when training volume, intensity, and performance metrics are logged digitally. Training apps used by Singapore gyms and personal trainers allow session-by-session tracking of sets, reps, loads, and performance notes, creating a searchable training history that informs programming decisions weeks and months into a client relationship.

For members without personal trainers, gym management apps that integrate with workout logging platforms provide self-directed access to the same structured tracking approach.

Artificial Intelligence in Singapore’s Fitness Industry

Artificial intelligence is beginning to influence fitness product and service design in Singapore, though its most sophisticated applications are still emerging rather than fully mainstream.

AI-powered training apps that generate personalised workout recommendations based on logged performance data, recovery metrics, and stated goals are increasingly available to Singapore consumers. These systems use machine learning to identify patterns in user data and adjust programme variables accordingly.

AI in equipment design is also advancing. Smart cardio equipment that adjusts resistance or pace based on real-time heart rate data, guiding the user to stay in a target training zone without manual adjustment, is available in Singapore’s premium gym segment.

Nutrition tracking platforms with AI-driven meal logging, including image recognition that identifies food items and estimates nutritional content from a photo, are highly relevant for Singapore’s food culture given the complexity of hawker dishes that do not appear in standard international food databases. Several platforms have developed Singapore-specific food databases that improve accuracy for local dishes.

Privacy and Data Protection for Fitness Technology Users in Singapore

Singapore’s Personal Data Protection Act (PDPA) governs how organisations collect, use, and store personal data, including health and fitness data generated by gym members and wearable device users. Singapore gym-goers who share biometric data through InBody assessments, app platforms, or wearable integration should be aware of their rights under the PDPA.

Key practical points for Singapore fitness technology users:

  • You have the right to access personal data held about you by a gym or fitness app, and to request correction of inaccurate data
  • Organisations collecting your health data must inform you of the purpose for which it is being used and obtain your consent
  • Data should not be retained longer than necessary for the stated purpose
  • You can withdraw consent for data collection, though this may affect access to data-dependent features

When evaluating fitness apps and gym platforms, reading the privacy policy for specifics on data sharing with third parties is a worthwhile step. Singapore’s regulatory environment provides reasonable protection, but informed data sharing decisions remain the individual’s responsibility.

TFX Singapore integrates technology meaningfully into the member experience through InBody analysis, digital class scheduling, and data-informed personal training, creating a training environment where decisions are guided by evidence rather than guesswork.

FAQ

Q: How accurate is InBody analysis compared to a DEXA scan for body composition?

A: DEXA (dual-energy X-ray absorptiometry) scanning remains the gold standard for body composition measurement and is more accurate than InBody BIA analysis for absolute values, particularly for bone density measurement. However, for the primary purpose most gym-goers need, tracking directional changes in muscle mass and body fat over time, InBody analysis is sufficiently accurate and significantly more practical. DEXA requires a medical facility, involves radiation exposure, and costs considerably more per assessment. InBody is available at the gym, takes 60 seconds, involves no radiation, and costs a fraction of DEXA. For trend tracking over weeks and months, InBody provides valuable and actionable data that serves the majority of Singapore gym-goers’ practical needs well.

Q: Does the order in which I wear my fitness tracker affect the data accuracy?

A: Most wrist-worn heart rate monitors are designed for the non-dominant wrist, which typically moves less during daily activity and provides a cleaner signal for resting heart rate and HRV measurements. During training, the accuracy of optical heart rate monitors varies by exercise type. Wrist-based heart rate tracking is less accurate during heavy resistance training with significant forearm and grip involvement, as the muscle contractions can interfere with the optical signal. For these sessions, a chest strap heart rate monitor provides significantly more accurate data. Many serious Singapore gym-goers use a chest strap during sessions and their wrist-based device primarily for daily HRV and sleep tracking.

Q: How should I interpret my HRV data as a Singapore gym-goer with a stressful job?

A: HRV interpretation is most meaningful relative to your own personal baseline rather than population averages. Your HRV is influenced by age, fitness level, and chronic stress in ways that make absolute values less informative than trends. Establish a baseline by recording your HRV daily for three to four weeks under consistent conditions, same time of day, immediately upon waking before getting out of bed. Significant drops below your established personal baseline, particularly sustained drops over several consecutive days, are the most reliable signal that recovery is compromised. For Singapore professionals with consistently high work stress, HRV baselines may be lower than population norms, and this is useful information about overall stress load rather than a limitation of the metric.

Q: Are Singapore’s food delivery and nutrition apps useful for tracking pre and post-workout nutrition?

A: Several nutrition tracking apps have made meaningful progress in Singapore food database accuracy, including Cronometer, MyFitnessPal, and local alternatives. However, accuracy for hawker dishes remains variable because the same dish prepared at different stalls has genuinely different nutritional composition depending on oil use, portion size, and specific ingredients. For precise calorie and macronutrient tracking, preparing meals with known ingredients and weights remains the most accurate method. For general nutritional awareness, these apps are useful even if the absolute numbers for local dishes are approximate. The greatest practical benefit is developing an intuitive understanding of the protein, carbohydrate, and fat content of common Singapore meals over time, which is more useful than obsessing over specific gram-level accuracy for any individual meal.

Q: Will fitness technology eventually replace personal trainers in Singapore gyms?

A: Technology will continue to augment what personal trainers can do, but the human elements of coaching are not replicable by current or near-future AI systems in meaningful ways. Motivation, real-time technique correction, accountability, and the relationship-based trust that makes coaching effective are all deeply human phenomena. What technology does is provide trainers with better data to inform programming decisions and allows members to stay connected to their progress between sessions. The trainers who thrive in Singapore’s evolving gym environment will be those who use technology as a tool to deepen the quality of the coaching relationship rather than viewing it as competition. For gym-goers, the optimal outcome is a trainer who understands both the human and data dimensions of your training, using technology to make the coaching smarter while maintaining the human connection that makes it sustainable.

read more
Social Media

How Storytelling Improves Social Media Engagement

The digital landscape is crowded with information. Every day, users scroll through miles of content, encountering aggressive sales pitches, corporate announcements, and product feature lists. In this environment of sensory overload, standard marketing messages often fail to register. The human brain has developed a natural filter for generic advertising, discarding dry data and promotional noise almost instantly.

To break through this wall of indifference, successful brands and content creators rely on an ancient human mechanism: storytelling. Long before the invention of the internet or printed text, stories served as the primary tool for passing down knowledge, building communities, and forming cultural bonds. When applied to social media, narrative structures transform cold commercial interactions into deeply personal human experiences. By shifting the focus from what a product does to how it impacts human lives, storytelling captures attention, inspires loyalty, and drives engagement metrics.

The Neurological Impact of Narrative Structures

To understand why stories perform so exceptionally well on social media, it is helpful to look at how the human brain processes information. When a user reads a list of product specifications or statistics, only two small areas of the brain are activated: Broca area and Wernicke area. These regions simply translate words into meaning, treating the text as an intellectual exercise.

When information is delivered as a structured narrative, the dynamic changes entirely. A compelling story activates multiple regions of the brain simultaneously, including the sensory cortex, the motor cortex, and the frontal lobe. The brain does not merely read the story; it attempts to experience it.

This neural simulation triggers the release of specific chemicals:

  • Cortisol: Generated during moments of narrative tension or conflict, cortisol focuses attention and sharpens analytical awareness.

  • Dopamine: Released when a story reaches a satisfying conclusion or a breakthrough moment, dopamine boosts memory retention and associates pleasure with the experience.

  • Oxytocin: Triggered by deep empathy for a character or a vulnerable situation, oxytocin fosters trust, social bonding, and a desire to connect.

On social media, this biochemical cocktail translates directly into user action. A user experiencing an oxytocin spike is far more likely to leave a meaningful comment, share the post with friends, or click a call-to-action link.

Deconstructing the Social Media Story Architecture

A common misconception is that a story must be long or complex to be effective. In the fast-paced realm of social media, where user attention spans are measured in seconds, stories must be concise, punchy, and structurally sound.

The Hook: Capturing the Infinite Scroll

On platforms like Instagram, TikTok, and X, the first two seconds determine whether a piece of content succeeds or fails. The hook is the opening sentence, video frame, or graphic element designed to disrupt the repetitive physical motion of scrolling. A powerful hook skips the pleasantries and dives straight into a compelling question, an unusual contradiction, or a moment of high tension.

The Conflict: Introducing the Friction

A story without conflict is merely an announcement. For a narrative to feel authentic and engaging, it requires friction. This is the point where the protagonist faces a hurdle, an unexpected failure, or a relatable frustration. In a business context, the conflict highlights the exact pain point that the target audience experiences every day.

The Resolution: Delivering the Transformation

The resolution brings the narrative arc to a satisfying close. However, the true focus of the resolution is not the product or service itself; it is the transformation. The story must clearly demonstrate how the protagonist moved from a state of frustration to a state of relief, success, or empowerment.

Strategic Storytelling Frameworks for Digital Platforms

Implementing narrative structures systematically requires framework models that align with the viewing habits of different digital audiences.

The Founder Journey Framework

Audiences on professional networking platforms like LinkedIn connect with people, not corporate logos. The founder journey framework humanizes an enterprise by pulling back the curtain on the behind-the-scenes struggles of building a business.

By sharing authentic stories of early product failures, late-night breakthroughs, and critical hiring mistakes, leaders build immense personal credibility. This transparency transforms a distant corporation into a relatable group of passionate individuals.

The Customer Catalyst Framework

Traditional case studies are often dry and clinical, relying heavily on percentages and corporate jargon. The customer catalyst framework converts these case studies into heroic narratives. The customer becomes the main character, facing a major threat or operational bottleneck. The brand acts merely as the helpful guide or tool that equips the hero to overcome the challenge. This approach allows prospective buyers to see themselves in the story, visualizing their own path to victory.

Micro-Narratives for Video

The explosion of short-form vertical video has birthed the micro-narrative. Within a sixty-second window, creators must execute a complete narrative arc. This is achieved by utilizing visual storytelling tricks, such as showing the finished, successful result in the first second before flashing back to the messy, difficult beginning. This technique creates an immediate curiosity gap, compelling the viewer to watch the entire video to understand how the transformation occurred.

Measuring Narrative Engagement Success

When transitions are made toward story-driven strategies, standard marketing metrics must be interpreted through a different lens. Traditional advertising focuses heavily on raw impressions and click-through rates. Storytelling, on the other hand, prioritizes deep qualitative engagement.

The Value of the Comment Section

The comment section serves as the ultimate barometer for narrative success. When a post relies on shallow clickbait, the comments are usually brief, containing simple phrases or generic emojis. When a post delivers a vulnerable, authentic story, the comment section transforms into a community forum. Users reply with long paragraphs, sharing their own parallel experiences and emotional reactions, which signals to platform algorithms that the content is highly valuable.

Amplification via Shares and Saves

A user sharing a post to their personal profile or sending it via direct message is the highest form of social media endorsement. People share stories because the narrative articulates an idea, an emotion, or a truth that they believe in but could not express as eloquently themselves. By sharing the story, the user uses the content to help define their own digital identity to their peers.

Frequently Asked Questions

Can storytelling be effective for boring B2B companies with technical products?

Storytelling is exceptionally valuable for technical B2B industries because it translates abstract concepts into tangible human outcomes. Instead of explaining data processing algorithms, a B2B company can tell the story of a stressed cybersecurity director who successfully saved their company from a massive data breach during a holiday weekend. Framing technology around human stakes makes complex products memorable.

How can a brand tell an effective story when platform character counts are strictly limited?

Short character limits require micro-storytelling techniques where single words or vivid images do the heavy lifting. A complete narrative arc can be achieved in a single sentence by focusing exclusively on a stark contrast. For instance, stating that a business started with a laptop in a crowded kitchen and just opened its fifth global office creates an instant mental image of struggle, growth, and triumph.

Does visual media require a different storytelling approach than text-based platforms?

Visual media relies on sensory cues to convey narrative elements instantly. While text-based platforms build scenes through descriptions and internal monologues, video and imagery use lighting, facial expressions, pacing, and audio design to set the emotional tone. The underlying narrative structure of hook, conflict, and resolution remains identical across both formats; only the delivery mechanisms differ.

What is the danger of using manufactured or exaggerated stories to boost engagement?

Modern social media audiences possess a high degree of skepticism and can spot artificial sincerity quickly. If a brand manufactures a false struggle or exaggerates a customer testimonial for dramatic effect, the truth will eventually emerge. A loss of authenticity destroys consumer trust instantly, causing severe, long-term damage to brand reputation that no clever marketing campaign can fix.

How does storytelling impact social media algorithm rankings over time?

Social media algorithms prioritize meaningful interaction and watch time over raw clicks. Because well-crafted stories naturally encourage users to linger on a post longer to read the text or watch a video to completion, dwell time metrics increase significantly. Platforms interpret this prolonged attention as a sign of premium quality, pushing the content to a broader audience segment.

How often should a brand post narrative content versus standard product promotions?

A balanced content matrix typically adheres to the eighty-twenty rule. Eighty percent of social media content should deliver value through storytelling, education, entertainment, or community building, while twenty percent is reserved for direct product promotion. Integrating promotional goals directly into stories ensures that even promotional content offers entertainment value.

read more
Technology

Why Your Fitness Tracker Feels Inconsistent, Measuring Real Progress From a BODYCOMBAT Training Routine

Wearable technology has changed how people perceive exercise. Heart rate graphs, calorie numbers, and recovery scores appear instantly after every workout, yet many BODYCOMBAT participants feel confused by what they see on their screens. A bodycombat class often produces wildly different readings from session to session, even when effort feels similar.

This article explains why tracking data during BODYCOMBAT can be misleading, what metrics actually matter, and how to use technology as a helpful guide rather than a source of frustration.

Why BODYCOMBAT challenges wearable accuracy

BODYCOMBAT combines fast strikes, explosive kicks, directional changes, and rhythm based movement. These characteristics make accurate tracking difficult for most wrist worn devices.

Common reasons for inconsistent data include:

  • Rapid arm movement disrupting optical sensors

  • Sudden heart rate spikes during combinations

  • Grip tension affecting blood flow at the wrist

  • Short recovery periods that confuse averaging algorithms

Because of this, two classes with similar effort may show very different calorie burn or intensity scores.

Calorie numbers and why they vary so much

Many people judge workouts by calorie burn, but this metric is one of the least reliable in high intensity group classes.

Calorie estimates are based on:

  • Heart rate trends

  • Body weight and age inputs

  • Algorithm assumptions about movement type

In BODYCOMBAT, heart rate fluctuates rapidly and movement patterns do not match steady cardio models. This leads to inflated or inconsistent numbers.

Rather than focusing on calories burned per session, it is more useful to look at trends across weeks.

Heart rate zones, what matters and what does not

Heart rate data is still useful when interpreted correctly. BODYCOMBAT naturally pushes participants into moderate to high intensity zones repeatedly.

Helpful ways to use heart rate data include:

  • Noting how quickly heart rate recovers between tracks

  • Observing average heart rate across the class

  • Tracking perceived effort alongside heart rate

Chasing maximum heart rate every session is unnecessary and often counterproductive. Consistent exposure to challenging but manageable intensity produces better adaptation.

Recovery between intervals as a progress marker

One overlooked metric is recovery speed. As fitness improves, heart rate drops faster between intense sections.

Signs of improvement include:

  • Faster breathing recovery

  • Lower heart rate after cooldown

  • Feeling ready sooner for the next track

These changes may not be reflected in calorie totals but indicate real cardiovascular progress.

Training load and weekly balance

Some wearables estimate training load based on intensity and duration. This can be useful when managing fatigue.

BODYCOMBAT sessions contribute significantly to weekly training load. Stacking too many high load days often leads to:

  • Declining performance

  • Poor sleep quality

  • Increased injury risk

Using training load trends helps balance high intensity days with lighter sessions and rest.

Step counts and movement outside the gym

Another misleading signal comes from step counts. After intense BODYCOMBAT sessions, daily steps may drop unintentionally.

This happens because:

  • Fatigue reduces spontaneous movement

  • People sit more after training

  • Mental tiredness limits activity

Monitoring steps or general movement helps ensure overall activity remains balanced, supporting fat loss and recovery.

Perceived effort versus device data

Technology should support awareness, not replace it. Perceived effort remains one of the most reliable indicators of training quality.

Ask simple questions after class:

  • Was today challenging but manageable

  • Could I maintain technique under fatigue

  • Do I feel energised or drained afterward

Comparing these answers with device data builds a more accurate picture over time.

Using wearable data to avoid burnout

Wearables can help identify early signs of overtraining if used wisely.

Warning signs include:

  • Elevated resting heart rate over several days

  • Declining heart rate variability trends

  • Poor sleep scores after repeated intense sessions

When these appear, reducing intensity or adding recovery days often restores balance quickly.

Tracking progress beyond numbers

Progress in BODYCOMBAT is not only physiological. Coordination, timing, and confidence improve gradually.

Signs of progress that devices cannot measure include:

  • Smoother transitions between movements

  • Better balance during kicks

  • Improved rhythm and flow

  • Reduced mental effort to follow choreography

These improvements translate to better performance and enjoyment.

Building a simple tracking framework

Rather than analysing every metric, focus on a few consistent indicators:

  • Weekly training frequency

  • Average session intensity

  • Recovery quality

  • Subjective energy levels

This simplified approach prevents data overload while still guiding smart decisions.

Technology as a tool, not a judge

Wearables are most effective when used as feedback tools rather than scorecards. BODYCOMBAT training success comes from consistency, recovery, and enjoyment, not perfect graphs.

Training environments that combine structured programming with education help members interpret data correctly. Facilities like True Fitness Singapore provide this balance by encouraging sustainable habits alongside performance tracking.

FAQ

Why does my calorie burn change every BODYCOMBAT session?

Wearables estimate calories based on heart rate patterns that vary with movement style and sensor accuracy.

Is heart rate tracking useless for BODYCOMBAT?

No. It is useful for observing trends and recovery, but not for precise calorie counts.

Should I use chest straps instead of wrist trackers?

Chest straps can improve accuracy, but perceived effort and recovery remain equally important.

How can I tell if I am improving without numbers?

Improved recovery speed, better coordination, and reduced fatigue are strong indicators of progress.

Can tracking too much affect motivation?

Yes. Over analysing data often increases stress and reduces enjoyment. Simpler tracking supports consistency.

How often should I review my data?

Weekly reviews are more useful than daily comparisons.

read more
Technology

B2B Content Marketing Tactics That Work

The Business-to-Business (B2B) buying journey has evolved into a complex, self-directed process. Modern enterprise buyers do not rely on traditional outbound sales calls or generic advertising campaigns to evaluate vendor software, platforms, or consulting services. Instead, they conduct deep, independent research long before contacting a sales representative. They browse industry publications, download white papers, read technical case studies, and evaluate analytical breakdowns to identify vendors capable of solving their unique operational friction points.

In this environment of self-sufficient procurement, a superficial digital presence is no longer effective. B2B content marketing requires a fundamental shift from self-promotional broadcasting to authoritative problem-solving. Success requires constructing a deliberate, data-driven content engine that addresses the multi-layered pain points of distinct organizational stakeholders. When executed with precision, strategic content marketing establishes structural credibility, shortens complex sales cycles, maximizes pipeline velocity, and drives measurable revenue growth.

Precision Persona Mapping and Intent-Based Content

Many B2B content campaigns fail because they target a broad, generic organization rather than the specific individuals responsible for procurement decisions. An enterprise buying committee typically includes multiple stakeholders, each evaluating a purchase through a completely different professional lens.

Deconstructing the Corporate Buying Committee

To create content that resonates, marketing teams must build distinct editorial strategies for each member of the internal purchasing committee:

  • The Technical Implementer (CTO, Head of Engineering): This stakeholder ignores marketing fluff and buzzwords. They demand highly technical documentation, API architecture blueprints, security compliance reviews, and clear proof that a system can scale seamlessly without adding technical debt.

  • The Financial Gatekeeper (CFO, VP of Procurement): This individual focuses entirely on economic impact. They require thorough cost-benefit analyses, calculated Return on Investment (ROI) models, total cost of ownership projections, and historical evidence of cost mitigation.

  • The End-User Manager (Director of Operations, Team Lead): This person cares about daily workflow efficiency. They want intuitive user interface walkthroughs, change-management blueprints, and case studies proving that the software reduces manual labor and improves overall employee productivity.

Leveraging Intent Data for Editorial Planning

Instead of guessing what topics to cover, sophisticated B2B marketers leverage search intent data and buyer telemetry. By analyzing search queries, forum discussions, and digital behavioral indicators, companies can determine exactly what obstacles prospective buyers face at various stages of their evaluation process. This ensures that every blog post, white paper, and video tutorial acts as a direct answer to an active market question.

Advanced Case Studies and Narrative Proof

Traditional B2B case studies are often dry, predictable, and heavily sanitized. They follow a simplistic formula: a customer had a minor problem, they bought our software, and everything became perfect. Modern enterprise buyers are highly skeptical of these idealized marketing narratives. They demand rigorous, transparent proof of capability.

The Friction-First Narrative Structure

An effective B2B case study must read like a compelling operational breakdown. It should devote significant real estate to the complexity of the initial problem, highlighting the hidden costs of inaction, internal structural roadblocks, and the specific limitations of alternative solutions.

By framing the customer as the main protagonist navigating an immense corporate hurdle, the vendor positions itself as the essential tool that empowered that success.

Uncompromising Data Transparency

Generic statements like our platform drastically improved efficiency carry no weight in professional procurement circles. Case studies must deliver granular, verified data points. Marketers must include exact numbers, such as a 42 percent reduction in infrastructure processing latency, 120 manual labor hours saved per week, or 1.4 million dollars in minimized operational overhead within the first fiscal quarter. Highlighting unexpected deployment challenges and how the customer service team resolved them actually improves trust and authenticity.


Thought Leadership and Proprietary Data Research

The internet is saturated with recycled content that merely rephrases ideas already available on top search results. To stand out as a true category leader, a B2B organization must generate original, proprietary insights that cannot be found anywhere else.

The Power of Industry Research Reports

One of the most effective tactics for building authoritative domain dominance is publishing annual, data-driven industry benchmark reports. By surveying hundreds of sector professionals, aggregating anonymized internal platform data, or running large-scale diagnostic studies, a company can uncover novel trends, macro operational shifts, and emerging industry bottlenecks.

These comprehensive reports become highly shareable digital assets. Industry journalists, corporate executives, and independent consultants will naturally cite these insights in their own presentations, articles, and board meetings, creating a continuous stream of premium organic backlinks and high-value inbound referrals.

Executive Insight Campaigns

B2B buyers want to do business with recognized experts, not faceless corporate entities. Content marketing strategies must include ghostwriting programs that transform internal corporate executives into distinct public voices on platforms like LinkedIn. By publishing opinionated, analytical pieces on industry regulations, macroeconomic trends, and future market predictions, leaders build immense personal and corporate brand equity.


Multi-Channel Content Distribution and Atomization

Creating a masterpiece of an analytical white paper is useless if the asset sits forgotten inside a hidden resource tab on a website. In modern B2B marketing, the content distribution strategy is just as vital as the content creation process.

The Content Atomization Framework

B2B marketing teams should never treat a piece of content as a single, isolated publication. Instead, they should utilize an atomization framework to break large, foundational research assets into dozens of smaller, highly consumable media pieces across multiple marketing channels:

  • The Foundational Asset: A comprehensive, sixty-page state of the industry research report.

  • The Sub-Assets: Six long-form editorial deep-dives exploring specific chapters or data anomalies from the report.

  • The Social Assets: Twenty-five short, chart-heavy LinkedIn text posts written from the perspective of company executives, alongside ten data-driven infographic slide presentations.

  • The Multimedia Assets: A four-part video panel series interviewing the industry experts who contributed to the initial survey data.

This systematic reuse of assets ensures that a single editorial investment continues to educate prospects across all available digital touchpoints for months at a time.


Frequently Asked Questions

What is the ideal balance between gated and ungated content in a B2B strategy?

A healthy B2B strategy employs a tiered approach. Top-of-funnel content, such as educational blog posts, thought leadership opinion pieces, and basic calculators, should remain completely ungated to maximize search engine optimization and brand visibility. High-value, deep-funnel assets that require substantial research investments, such as proprietary industry reports, advanced software toolkits, or comprehensive video masterclasses, should be gated behind a short lead-generation form to capture contact details for sales pipeline development.

How does account-based content marketing differ from standard B2B content tactics?

Standard B2B content tactics target an entire industry or demographic group broadly. Account-Based Marketing (ABM) content is highly localized and tailormade for a specific shortlist of high-value target corporations. In an ABM campaign, content creators write articles, build dashboards, or produce video teardowns that reference a specific target company by name, addressing their exact known organizational structure, technology stack, and public corporate challenges directly.

Why do standard call-to-action buttons like schedule a demo often fail on top-of-funnel content?

Forcing a user to commit to a live sales demo when they have just discovered a brand through an educational blog post introduces immense psychological friction. At the top of the funnel, buyers are looking for objective information, not a sales pitch. Top-of-funnel content should use low-friction calls-to-action, such as inviting the reader to subscribe to a weekly educational newsletter, check out a parallel case study, or download a free checklist.

How do you measure the financial return on investment of a long-form thought leadership article?

Measuring the ROI of thought leadership requires looking past immediate click-through conversion templates to track assisted conversions and pipeline acceleration. Marketers utilize advanced marketing automation attribution models to see if high-value closed-won accounts read specific thought leadership pieces during their multi-month buying journey, or if deals exposed to those leadership pieces closed faster and with higher contract values.

What role do podcasts play in modern B2B content marketing?

Podcasts serve as a powerful tool for deep audience engagement and relational business development. Hosting an industry podcast allows a B2B company to invite high-profile prospects and key market influencers on the show as interview guests, building immediate professional relationships. For the listening audience, long-form audio conversations provide a convenient way to consume sophisticated industry advice during commute or workout times, building deep multi-hour brand familiarity.

How should a B2B company handle content creation if the subject matter is highly technical?

To produce accurate content in technical industries like biotechnology or enterprise infrastructure engineering, general marketing copywriters should not write the material in isolation. The marketing department must act as journalists, conducting internal interviews with Subject Matter Experts (SMEs), engineers, and product developers within the company. The copywriters then translate those technical insights, raw transcripts, and system data into polished, structured, and highly readable content assets.

read more
Web Service

Architecting Scalable Microservices for High-Traffic Web Services

Building web services that can seamlessly handle millions of concurrent users is one of the most significant challenges in modern software engineering. When traffic spikes during a product launch, a global news event, or a flash sale, traditional monolithic architectures often struggle under the weight of resource contention. A single bottleneck can bring down the entire application.

Microservices architecture addresses this vulnerability by breaking a large application into a collection of smaller, loosely coupled services. Each service handles a discrete business capability and operates independently. However, simply dividing an application into smaller pieces does not guarantee scalability. True high-availability and horizontal scalability require deliberate architectural patterns, robust data management strategies, and rigorous traffic coordination.

Core Architectural Patterns for Scalability

To build a microservice ecosystem capable of handling immense traffic, engineers must implement patterns that isolate failures, maximize resource utilization, and minimize latency.

The API Gateway Pattern

An API gateway serves as the single entry point for all client requests. Instead of clients calling dozens of individual microservices directly, they route requests through the gateway.

The gateway performs several critical high-traffic functions:

  • Reverse Proxying: Routing requests to the appropriate backend microservices.

  • Load Balancing: Distributing incoming traffic evenly across multiple instances of a service.

  • Rate Limiting and Throttling: Shielding downstream services from overwhelming traffic spikes or malicious Denial of Service (DoS) attacks.

  • Cross-Cutting Concerns: Handling authentication, SSL termination, and logging in a centralized location, freeing up individual microservices to focus purely on business logic.

Asynchronous Event-Driven Architecture

In high-traffic systems, synchronous communication (like HTTP REST calls between services) can create a dangerous chain reaction. If Service A must wait for Service B, which is waiting for Service C, latency compounds. If Service C fails, the entire chain collapses.

Replacing synchronous chains with asynchronous, event-driven communication solves this issue. Services publish events to a distributed message broker (such as Apache Kafka or RabbitMQ) when an action occurs. Downstream services consume these messages at their own pace. This decouples the services, ensuring that a temporary traffic spike or a slowdown in one service does not degrade the performance of the upstream components.

The Circuit Breaker Pattern

High traffic amplifies failures. If a downstream database or third-party API slows down, upstream services will continue to send requests, exhausting thread pools and memory.

The circuit breaker pattern prevents this systemic failure. When a service detects that a dependent component is failing or timing out consistently, the circuit “opens.” Instead of waiting for a timeout, subsequent calls fail fast immediately, returning a fallback response or a cached value. This gives the struggling downstream component time to recover under heavy load.

Data Management Strategies under Heavy Load

Monolithic applications typically rely on a single, massive relational database. Under high traffic, this database becomes the ultimate bottleneck due to lock contention and CPU exhaustion. Microservices require a decentralized approach to data.

Database per Service and Polyglot Persistence

Each microservice must own its data store, completely isolated from other services. This prevents tight coupling and allows teams to scale their storage layers independently. Furthermore, it enables polyglot persistence, which means choosing the right database technology for the specific workload:

  • Relational Databases (PostgreSQL, MySQL): Ideal for services requiring complex transactions, strict ACID compliance, and structured data (e.g., billing or user accounts).

  • NoSQL Key-Value/Document Stores (MongoDB, Cassandra, DynamoDB): Optimized for high-throughput, horizontal scalability, and low-latency writes (e.g., user sessions, product catalogs).

  • Graph Databases (Neo4j): Best for handling highly interconnected data networks (e.g., recommendation engines or social graphs).

Distributed Caching Strategies

The fastest database query is the one you never have to make. Caching is mandatory for high-traffic services to reduce database load and slash response times.

A multi-tiered caching strategy is highly effective:

  • In-Memory Local Cache: Storing frequently accessed, immutable data directly within the microservice memory container for sub-millisecond retrieval.

  • Distributed Cache (Redis, Memcached): A shared, high-performance caching layer accessible by all instances of a microservice. This ensures data consistency across scaled-out containers.

Engineers must carefully design cache invalidation strategies, such as Write-Through or Cache-Aside, to balance performance against data freshness.

Infrastructure, Deployment, and Autoscaling

An elegant software architecture means little if the underlying infrastructure cannot adapt to fluctuating traffic patterns dynamically.

Containerization and Orchestration

Microservices should be packaged as lightweight containers using tools like Docker. Containers ensure consistency across development, testing, and production environments.

To manage thousands of containers across a cluster of virtual or physical machines, an orchestration platform like Kubernetes is necessary. Kubernetes automates container deployment, networking, and service discovery, ensuring that traffic is always routed to healthy, running instances of a microservice.

Horizontal Autoscaling Mechanisms

Static infrastructure either wastes money during low-traffic periods or crashes during unexpected traffic surges. High-traffic web services leverage autoscaling to adjust capacity on the fly.

Autoscaling functions across two distinct layers:

  • Horizontal Pod Autoscaler (HPA): Monitors metrics like CPU utilization, memory consumption, or custom application metrics (e.g., request count per second) and automatically provisions or terminates microservice containers to meet demand.

  • Cluster Autoscaler: Scales the underlying cloud infrastructure (virtual machines) up or down when the orchestration layer requires more physical compute resources to host the new containers.

Observability and Monitoring

You cannot optimize what you cannot measure. In a distributed microservices environment, diagnosing a performance bottleneck or an error requires specialized observability tools.

Distributed Tracing

When a user click triggers a workflow that touches ten different microservices, standard monolithic logs are useless. Distributed tracing tools (such as OpenTelemetry, Jaeger, or Zipkin) inject a unique correlation ID into the HTTP header or metadata of the initial request. As the request propagates through the network, every service logs events using that same ID. Engineers can then visualize the entire lifecycle of a request, pinpointing exactly which service caused a delay or threw an exception.

Centralized Logging and Metrics Collection

Individual container logs are ephemeral and vanish when a container scales down. High-traffic systems aggregate logs into a centralized repository using tools like Elasticsearch, Logstash, and Kibana (the ELK stack). Simultaneously, time-series monitoring tools like Prometheus collect infrastructure and application metrics, feeding real-time dashboards in Grafana to alert engineering teams before performance degradation impacts end users.

Frequently Asked Questions

How do you maintain data consistency across multiple microservices without distributed transactions?

Instead of relying on heavy distributed transactions (like two-phase commit), which degrade performance under high traffic, engineers use the Saga Pattern. A Saga is a sequence of local transactions. Each local transaction updates data within a single service and publishes an event. If a step fails, the Saga executes compensating transactions that explicitly undo the changes made by the preceding steps, ensuring eventual consistency.

What is the difference between horizontal scaling and vertical scaling in microservices?

Vertical scaling, or scaling up, means adding more power (CPU, RAM) to an existing server or container. Horizontal scaling, or scaling out, means adding more instances of the server or container to share the workload. Horizontal scaling is preferred for high-traffic microservices because it has no theoretical upper limit and prevents a single point of failure.

How does service discovery work when microservices are constantly autoscaling?

Because containers are continually created and destroyed during autoscaling, their IP addresses change dynamically. Service discovery tools, such as Consul or the native Kubernetes DNS system, maintain a real-time registry of all active, healthy service instances. When Service A needs to talk to Service B, it queries the service registry to get a valid, operational IP address.

What is a service mesh and when should it be implemented?

A service mesh (like Istio or Linkerd) is a dedicated infrastructure layer injected alongside microservices to handle service-to-service communication. It manages traffic encryption, mutual TLS (mTLS), advanced routing, and telemetries automatically via sidecar proxies. It should be implemented when a microservices ecosystem grows so large that managing security and traffic rules inside individual service code becomes unmanageable.

How do you handle database migrations in an autoscaling microservices environment?

Database changes must be completely backward-compatible to avoid breaking active, autoscaling containers. Engineers utilize the Expand and Contract pattern. First, the database is expanded (e.g., adding a new column while keeping the old one). Next, a new version of the microservice is deployed to read from the old column and write to both. Once all old containers are replaced and data is migrated, a final database script contracts the schema by removing the old column.

What is gRPC and why is it used instead of REST for internal microservice communication?

gRPC is a high-performance, open-source remote procedure call framework developed by Google. It uses HTTP/2 for transport and Protocol Buffers for binary serialization, whereas REST typically uses HTTP/1.1 and JSON text. Because gRPC payloads are much smaller and connection multiplexing is native to HTTP/2, it significantly reduces latency and network overhead during internal, service-to-service communication under heavy loads.

read more
Social Media

Continuous Integration Strategies Explained

In the early days of software engineering, development teams worked in isolation for weeks or months at a time. Each engineer built their assigned features on localized branches, far removed from the work of their peers. When the time arrived to merge these disparate codebases into a single release, teams inevitably encountered an era of prolonged frustration known as merge hell. Conflicting code changes, broken dependencies, and hidden architectural bugs took days or weeks to unravel.

Continuous Integration (CI) emerged as a direct solution to this operational bottleneck. It is a software development practice where engineers merge their code changes into a central repository frequently, often multiple times a day. Each integration triggers an automated build and test sequence to verify the integrity of the new code. By shifting validation to the earliest stages of the development lifecycle, teams can identify and resolve defects rapidly, improve software quality, and dramatically accelerate release cycles.

Core Pillars of a Successful Continuous Integration Strategy

Implementing a continuous integration strategy requires more than installing a CI tool and writing a build script. It demands a cultural shift and adherence to fundamental technical engineering pillars.

A Single Source of Truth

Every successful CI strategy relies on a centralized version control system, such as Git. Every piece of code, configuration script, database schema migration, and environment variable blueprint must live within this repository. If a component is necessary to build, test, or run the application, it must be tracked by version control. This ensures that the automated CI environment exactly mirrors the parameters intended by the development team.

Automated Build Execution

The moment an engineer pushes code to the central repository, the CI server must automatically detect the change and initiate a build. A build compiles the source code, bundles assets, resolves external dependencies, and packages the application into an executable format. If the code fails to compile or contains syntax errors, the build fails immediately, notifying the developer before the corrupted code can impact anyone else.

Comprehensive Automated Testing

An automated build that compiles successfully proves that the code is syntactically correct, but it does not prove that the code functions correctly. A robust CI strategy incorporates a tiered testing pipeline that executes automatically during every build:

  • Unit Tests: These isolate and validate individual functions, methods, or classes. They execute in seconds and form the baseline foundation of the testing matrix.

  • Integration Tests: These verify that different modules, subsystems, or external service mockups interact correctly with one another.

  • Static Code Analysis: Tools inspect the codebase for security vulnerabilities, style violations, and code smell metrics without executing the application.

Technical Branching Strategies for Continuous Integration

The effectiveness of a CI pipeline depends heavily on how a development team organizes and manages its version control branches. Different architectural workflows offer distinct advantages depending on team size and project maturity.

Trunk-Based Development

Trunk-based development is the gold standard branching strategy for mature continuous integration. In this model, all developers commit their code directly to a single branch, usually called the main or trunk. Branches are either nonexistent or extremely short-lived, lasting no more than a few hours before being merged back into the trunk.

Because everyone works on the same branch, integration occurs constantly. Hidden merge conflicts are eliminated, and developers are forced to write highly modular code. To prevent unfinished features from breaking production, engineers rely on feature flags, which encapsulate new logic behind an intentional configuration switch that remains turned off until the feature is fully verified.

GitFlow Architecture

GitFlow is a more structured, traditional branching model that utilizes multiple long-lived branches for distinct purposes. The repository maintains a main branch for production-ready code and a develop branch for integration. Engineers create dedicated feature branches off the develop branch and work on them independently.

While GitFlow provides strict control over what code enters production, it presents challenges for true continuous integration. Because feature branches can live for days or weeks, the integration process is delayed, increasing the likelihood of significant merge conflicts when the feature branch is finally brought back to the develop branch.

Optimizing CI Pipelines for Speed and High Throughput

As a software project grows, the size of the codebase increases, the number of automated tests multiplies, and the CI build time naturally extends. A slow CI pipeline frustrates developers, stalls productivity, and defeats the primary purpose of rapid feedback loops. Optimizing pipeline throughput is essential.

Parallel Test Execution

Running hundreds of integration and unit tests sequentially is highly inefficient. Modern CI strategies utilize parallelization to split the testing suite across multiple isolated execution runners or containers simultaneously. For example, if a testing suite takes thirty minutes to run end-to-end, splitting the tests intelligently across six parallel containers can reduce the total execution time down to roughly five minutes.

Intelligent Caching Mechanisms

A significant portion of build time is often consumed by downloading external package dependencies, compiling standard libraries, and configuring runtime environments. By implementing a caching strategy within the CI runner framework, the pipeline can store these dependencies between runs. The system only invalidates and redownloads the cache when the underlying dependency configuration file is explicitly modified, saving valuable processing time on everyday commits.

Test Impact Analysis

Test impact analysis is an advanced optimization strategy where the CI system uses code coverage data to determine exactly which files were modified in a specific commit. Instead of executing the entire testing suite for a minor text edit, the CI server intelligently selects and executes only the specific unit and integration tests that are directly or indirectly impacted by the modified code paths.

Overcoming Cultural and Operational Barriers

The technical implementation of a continuous integration pipeline is only half the battle; the human and cultural elements are equally critical to preventing system breakdown.

The Broken Build Rule

A fundamental law of continuous integration states that the trunk branch must always remain in a stable, buildable state. If a developer pushes code that triggers a pipeline failure, fixing that build becomes the absolute highest priority for the entire team. No developer should merge additional code on top of a broken build, as doing so compounds the error and makes identifying the root cause of the initial failure significantly harder.

Frequent Commits

Continuous integration cannot function if developers write code locally for an entire week before pushing it to the server. Engineers must break down complex features into tiny, incremental milestones that can be committed and integrated multiple times a day. This practice ensures that the delta between the developer’s local workspace and the central repository remains microscopic, making conflict resolution trivial.

Frequently Asked Questions

What is the precise technical distinction between Continuous Integration and Continuous Delivery?

Continuous Integration focuses entirely on the early stages of the development cycle, specifically automated building, static analysis, and comprehensive verification testing every time code is committed. Continuous Delivery extends this process by automatically packaging the validated build artifact and staging it so that it is technically ready to be deployed to a production environment at any given moment with a manual, single-button approval.

How do feature flags assist in a continuous integration environment?

Feature flags allow developers to integrate unfinished code directly into the main branch without exposing incomplete features to end-users. By wrapping new logic inside a conditional statement driven by a remote configuration file, engineers can continually merge and test their code structural patterns within the live system while keeping the user-facing component safely hidden until it passes all operational criteria.

What are flaky tests and how do they impact a continuous integration pipeline?

A flaky test is an automated test that exhibits non-deterministic behavior, meaning it passes or fails intermittently on the exact same codebase without any structural changes to the underlying logic. Flaky tests are destructive to a CI strategy because they erode developer trust in the pipeline. When developers begin assuming that failures are just pipeline flukes rather than genuine bugs, critical defects slip into production unnoticed.

Why should static code analysis be placed early in the CI build sequence?

Static code analysis tools should run at the very beginning of the validation sequence because they do not require compiling or launching the full application framework. They can scan the raw text files for security flaws, styling deviations, and formatting errors within seconds. Catching these trivial issues early allows the pipeline to fail fast, saving compute resources that would otherwise be wasted on long-running integration tests.

How do you handle continuous integration for legacy monolithic applications that lack automated tests?

Transitioning a legacy monolith to a CI strategy requires a gradual approach known as the strangler pattern or incremental coverage. Teams should not halt development to write thousands of retroactive tests. Instead, they establish a baseline rule that any new code written or any bug fixed moving forward must be accompanied by corresponding automated tests, allowing coverage to expand organically over time.

What role do container technologies play in modern continuous integration strategies?

Container tools like Docker ensure environmental consistency across the entire pipeline. Instead of running tests directly on a fluctuating host server virtual machine, the CI pipeline initializes standardized containers defined by immutable configuration files. This guarantees that the code is built and tested inside an environment that is identical to the developer’s local machine and the final production servers, eliminating environmental discrepancies.

read more
Web Service

How the best B2B web design agencies Use Calculators and Interactive Tools

Interactive tools can help business buyers explore costs, savings, product suitability, capacity, or implementation requirements. When designed carefully, they turn complex information into a practical experience. Poorly planned tools may create misleading results or unnecessary friction.

The best B2B web design agencies are often assessed by how their work balances brand presentation, accessible navigation, responsive layouts, and clear communication for different business audiences.

Start With a Useful Decision

A tool should help the visitor answer a meaningful question.

Examples include estimating potential costs, identifying a suitable configuration, assessing readiness, or comparing service levels. The result should support a real buying task.

Building an interactive feature solely to make the website appear innovative rarely creates lasting value.

Define Inputs Carefully

Every requested input should contribute to the result.

Labels need to be understandable, and unfamiliar terms should include explanations. Default values can help visitors begin, but they should not hide assumptions.

The tool should accept realistic ranges and respond appropriately to incomplete or unexpected entries.

Explain the Calculation

Business buyers may question results if the method is invisible.

A concise explanation can identify the assumptions, data basis, and factors not included. Detailed methodology may be available separately when the calculation is complex.

Transparency improves credibility and prevents estimates from being mistaken for guaranteed outcomes.

Provide Useful Results

Results should explain what the number or recommendation means.

Charts, comparisons, ranges, and written interpretation can make the output easier to understand. The tool may also suggest relevant products, services, or resources.

The presentation should avoid implying certainty when the result depends on limited inputs.

Design for Mobile Devices

Forms and interactive controls often become difficult to use on smaller screens.

Fields need clear labels, sufficient spacing, and suitable input formats. Tables and charts should adapt without requiring excessive horizontal scrolling.

Testing should include touch controls, different screen sizes, and slower connections.

Maintain Accessibility

Interactive tools should support keyboard navigation, visible focus states, readable contrast, descriptive error messages, and understandable results.

Important information should not depend only on colour or animation.

Alternative formats may be needed when complex visualisations cannot communicate adequately through assistive technologies.

Decide When to Request Contact Details

Requiring personal information before showing any result can discourage participation.

The company might provide the initial result openly and offer a detailed report or consultation in exchange for contact information.

Visitors should understand how their information will be used and what communication may follow.

Connect With Sales Appropriately

A completed assessment may provide useful context for a sales conversation.

With appropriate consent, the tool can transfer relevant inputs and results into the enquiry process. Sales representatives can then respond to the customer’s actual situation.

The company should avoid treating every anonymous interaction as immediate buying intent.

Plan for Maintenance

Pricing, assumptions, products, and industry conditions may change. The tool needs a named owner and review schedule.

Technical monitoring should identify calculation failures and integration problems. Results should be retested whenever the underlying logic changes.

An interactive tool succeeds when it simplifies a genuine business decision. Clear inputs, transparent assumptions, useful results, accessibility, and ongoing maintenance turn the feature into a practical part of the B2B buying experience.

read more
Technology

The Growing Impact of Self-Learning Algorithms on Modern Product Design

Introduction

Self-learning algorithms have become a defining force in modern product development. By analyzing user behavior, predicting needs, and adapting in real time, these systems are transforming how companies conceptualize, build, and refine products. The outcome is a design landscape that moves faster, responds smarter, and delivers more personalized experiences than ever before.

How Self-Learning Algorithms Work in Product Design

Self-learning models—often powered by machine learning, deep learning, and reinforcement learning—process large data sets to uncover patterns that inform design decisions.

Key Capabilities

  • Pattern recognition: Identifying design features users prefer.

  • Predictive modeling: Forecasting how new features will perform.

  • Optimization: Continuously improving design choices based on live feedback.

  • Automation: Streamlining repetitive tasks like prototyping and testing.

These capabilities reduce guesswork, allowing designers to rely on evidence-backed insights.

Transforming the Product Development Process

Enhanced User-Centered Design

Self-learning systems analyze behavioral data from millions of interactions. This helps designers understand:

  • Where users struggle

  • Which features are underused

  • What improvements could increase engagement

As a result, products evolve based on real user needs rather than assumptions.

Faster Iterations and Prototyping

Algorithms can simulate countless design scenarios in minutes. This enables:

  • Rapid A/B testing

  • Real-time adaptation to user feedback

  • Automated generation of alternative design concepts

Speeding up iteration cycles reduces time-to-market and boosts competitiveness.

Personalized Product Experiences

One of the most powerful impacts is hyper-personalization. With self-learning algorithms:

  • Interfaces adjust to user behavior

  • Product recommendations feel intuitive

  • Features adapt dynamically to individual preferences

This level of personalization increases satisfaction and long-term loyalty.

Predictive Maintenance and Lifecycle Optimization

For physical products, algorithms can predict when components will fail, helping companies design:

  • More durable materials

  • Smarter maintenance systems

  • Efficient upgrade cycles

This not only improves performance but also reduces waste.

Industries Leading the Adoption

Consumer Technology

Smartphones, wearables, and digital apps rely heavily on AI-driven design to refine interfaces and tailor content.

Automotive Design

Self-learning tools help optimize aerodynamics, driving experience, and safety systems through simulation and real-time learning.

Healthcare Devices

Medical product designers use machine learning to enhance diagnostic tools, improve usability, and personalize treatment paths.

Industrial and Manufacturing Products

Algorithms refine product geometry, reduce material use, and streamline production systems.

Challenges and Ethical Considerations

Data Privacy Concerns

Since these algorithms rely on extensive user data, companies must ensure:

  • Secure data handling

  • Transparent data use policies

  • Compliance with global privacy regulations

Potential Bias in Design

Algorithms learn from available data—if the data is biased, the design outcomes may be too. Continuous monitoring is essential to maintain fairness.

Balancing Creativity and Automation

While automation accelerates innovation, human creativity remains irreplaceable. Designers must leverage algorithms as supportive tools, not creative substitutes.

The Future of Self-Learning Algorithms in Product Design

Over the next decade, we can expect:

  • Fully automated design cycles with human oversight

  • More intuitive, adaptive product ecosystems

  • Seamless integration of virtual and physical design environments

  • Increased collaboration between AI systems and human designers

The synergy of human intuition and machine intelligence will define the next generation of groundbreaking products.

FAQs

1. How do self-learning algorithms differ from traditional design software?

Traditional tools follow preset rules, while self-learning algorithms evolve through data and adapt over time.

2. Can small businesses benefit from AI-driven product design?

Yes. Cloud-based AI tools have lowered costs, making advanced capabilities accessible to startups and small teams.

3. Do algorithms replace human designers?

No. They enhance decision-making but do not replicate human creativity or strategic thinking.

4. What kind of data is needed for effective algorithm training?

User interaction data, performance metrics, environmental conditions, and historical design outcomes are commonly used.

5. How can designers ensure algorithm-driven designs are unbiased?

Regular audits, diverse datasets, and ethical oversight help reduce bias.

6. Are self-learning algorithms useful for physical products, not just digital ones?

Absolutely. They are used in materials optimization, structural design, automotive engineering, and more.

7. What skills should modern designers develop to work with these technologies?

A strong understanding of data literacy, algorithmic thinking, and human-AI collaboration techniques is increasingly valuable.

read more
Technology

Autonomous Coding Tools: Will Developers Become Supervisors?

The rapid evolution of autonomous coding tools is redefining what it means to be a software developer. With systems capable of generating, testing, and optimizing code independently, many wonder whether developers are shifting from hands-on creators to strategic supervisors. The reality is more nuanced: these tools are transforming workflows, responsibilities, and expectations—but not eliminating the need for human expertise.

The Rise of Autonomous Coding Systems

AI Beyond Assistance

Earlier AI tools acted as assistants, offering suggestions or autocompleting snippets. Today’s autonomous platforms go further by:

  • Generating complete features from specifications

  • Running tests and reporting failures

  • Refactoring codebases with minimal guidance

  • Detecting performance bottlenecks

  • Proposing architectural improvements

This leap positions AI not just as a supportive utility, but as an active participant in the development cycle.

Why Adoption Is Accelerating

Key forces behind this shift include:

  • Demand for faster delivery cycles

  • Shortage of skilled engineers

  • Rising complexity in software ecosystems

  • Economic pressure to reduce operational costs

As organizations integrate these tools, they are discovering new workflows built around collaboration between human judgment and automated execution.

Developers as Supervisors: A New Role Emerges

Oversight Over Manual Production

Rather than replacing developers, autonomous systems redistribute responsibilities. Engineers now focus on:

  • Ensuring AI-generated outputs meet business requirements

  • Reviewing code for security and compliance

  • Making architectural decisions

  • Curating data and prompts for AI performance

  • Coordinating multi-agent development pipelines

In this model, developers shift from writing every line of code to supervising the systems that generate the code.

Quality Assurance Takes Center Stage

Autonomous tools excel at speed but still struggle with:

  • Contextual understanding

  • Ethical implications

  • Long-term maintainability

  • Complex edge cases

Human supervisors catch these gaps, validating that AI-driven changes align with organizational standards.

Benefits of the Supervisory Model

Increased Productivity

When AI handles repetitive or boilerplate tasks, developers can spend more time on:

  • Creative problem-solving

  • Feature innovation

  • Systems design

  • Scaling infrastructure

Higher Code Consistency

Autonomous tools can enforce uniform:

  • Formatting

  • Documentation

  • Test coverage

  • Security patterns

Reduced Development Costs

By automating large portions of the coding workload, teams can deliver more with fewer resources, especially in high-complexity projects.

Challenges That Still Require Human Leadership

Trust and Reliability

AI systems may produce elegant-looking code that fails silently or introduces long-term technical debt.

Security Vulnerabilities

Autonomous generation can lead to:

  • Insecure libraries

  • Logic flaws

  • Non-compliance with regulations

Human oversight remains essential for risk mitigation.

Cultural Resistance

Developers may fear displacement or distrust AI-driven tooling. Successful adoption requires:

  • Clear communication

  • Upskilling

  • Redefined responsibilities

Accountability Questions

When AI writes a significant portion of the code, who is responsible for failures? The organization still relies on human supervisors to answer this question.

The Future: Collaboration, Not Replacement

Developers Will Still Be Central

Even as coding becomes increasingly automated, the software industry will continue to rely on people who:

  • Understand complex systems deeply

  • Design architectures AI can follow

  • Translate business logic into requirements

  • Make ethical and strategic decisions

AI expands developers’ capabilities rather than rendering them obsolete.

A Hybrid Workflow Becomes Standard

The likely outcome is a co-pilot ecosystem where:

  • AI handles generation, refactoring, and testing

  • Developers handle oversight, direction, and high-level engineering

In this future, developers don’t disappear—they evolve.

FAQs

1. Will autonomous coding tools replace developers entirely?

No. These tools automate repetitive tasks, but developers remain essential for strategy, architecture, and oversight.

2. What skills will developers need in an AI-driven environment?

Critical thinking, systems design, prompt engineering, and AI supervision will become increasingly important.

3. Can autonomous tools write production-level code reliably?

They can generate strong code, but human review is still needed to ensure security, compliance, and maintainability.

4. How do autonomous coding tools impact software quality?

Quality often improves due to consistent patterns and rapid testing, though AI mistakes still require human correction.

5. Are certain developer roles more affected than others?

Roles involving repetitive coding tasks face the biggest shift, while architecture and leadership roles gain prominence.

6. What industries benefit most from autonomous coding?

Finance, healthcare, SaaS, and large-scale enterprise systems gain significant advantages due to high complexity and tight timelines.

7. Will coding still be a valuable career in the next decade?

Yes—though the focus will shift toward supervising AI-driven pipelines and solving higher-order technical challenges.

read more
1 2 3 4 … 30
Page 2 of 30